


Web Scraper API
Fetch real-time data from 100+ websites,No development or maintenance required.
SCRAPING SOLUTIONS
Get accurate and in real-time results sourced from Google, Bing, and more.
With 120+ prebuilt and custom scrapers ready for any use case.
No blocks, no CAPTCHAs—unlock websites seamlessly at scale.
Execute scripts in stealth browsers with full rendering and automation
PROXY INFRASTRUCTURE
Over 100 million real residential IPs from genuine users across 190+ countries.
Reliable mobile data extraction, powered by real 4G/5G mobile IPs.
For time-sensitive tasks, utilize residential IPs with unlimited bandwidth.
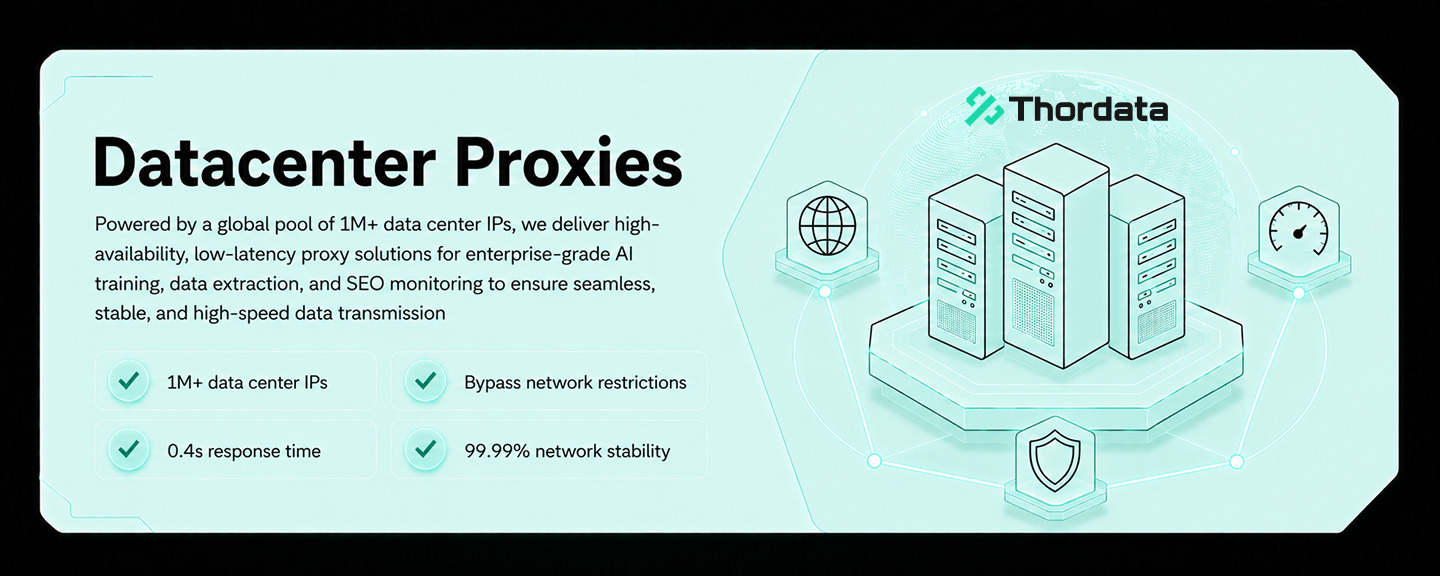
Fast and cost-efficient IPs optimized for large-scale scraping.
SCRAPING SOLUTIONS
PROXY INFRASTRUCTURE
DATA FEEDS
Full details on all features, parameters, and integrations, with code samples in every major language.
LEARNING HUB
ALL LOCATIONS Proxy Locations
TOOLS
RESELLER
Get up to 50%
Contact sales:partner@thordata.com
Products $/GB
Fetch real-time data from 100+ websites,No development or maintenance required.
Get real-time results from search engines. Only pay for successful responses.
Execute scripts in stealth browsers with full rendering and automation.
Bid farewell to CAPTCHAs and anti-scraping, scrape public sites effortlessly.
Dataset Marketplace Pre-collected data from 100+ domains.
Over 100 million real residential IPs from genuine users across 190+ countries.
Reliable mobile data extraction, powered by real 4G/5G mobile IPs.
For time-sensitive tasks, utilize residential IPs with unlimited bandwidth.
Fast and cost-efficient IPs optimized for large-scale scraping.

Data for AI $/GB
Pricing $0/GB
Docs $/GB
Full details on all features, parameters, and integrations, with code samples in every major language.
Resource $/GB
EN $/GB
产品 $/GB
AI数据 $/GB
定价 $0/GB
产品文档 $/GB
资源 $/GB
简体中文 $/GB
Property-data collection RFPs ask the wrong questions in 90% of drafts (“How many IPs do you have?” “Can you scrape Zillow?”), and vendors answer them without anyone noticing the questions that determine project survival — coverage semantics, geo fidelity, change-detection economics, and structured-field depth — went unasked. This is a real estate data RFP read line by line, with a good answer, a red flag, and the architecture behind it.
If you’re a proptech data lead, a brokerage analytics team, or a market-research firm assembling listing data, you’ve drafted this document before. Let’s annotate it.
What the RFP means: coverage of the platforms that matter plus the long tail that differentiates you.
A good answer distinguishes the two tiers explicitly. For the majors: pre-built scrapers with structured field extraction (price, beds, baths, square footage, days-on-market, status, image sets), not raw HTML hand-offs. Thordata’s catalog covers 120+ pre-built targets including Zillow, with results delivered as JSON, CSV, or XLSX at roughly $0.50–$1.00 per 1,000 results — and the field schema is stable across portal redesigns, because parser maintenance is the vendor’s bill, not yours. For the MLS long tail: raw residential proxy capability with the same account and dashboard, city-targeted where the MLS is city-scoped, at published volume pricing ($2.00/GB down to $0.65/GB).
Red flag: an answer that promises “any site” without distinguishing which are maintained scrapers versus which are your engineering problem.
What the RFP means: geo fidelity, and it’s quietly the hardest requirement in the document.
Property markets are hyper-local, and portal behavior is location-sensitive: what a search returns from a Phoenix IP differs from a Phoenix-residential IP on mobile. Centralized collection produces “average Arizona” data for a Phoenix product. The correct answer names targeting granularity — country, state, city, and ASN-level, without surcharge — and session behavior: sticky sessions for search-and-paginate flows (Thordata supports up to 90 minutes) so a full result set comes from one coherent session, not forty unrelated ones.
A good answer also volunteers how it proves this: exit-IP verification on sample runs, geo-match rates, and a willingness to let you audit a metro with your own local testers. Red flag: “we have 195 countries” as an answer to a question about Phoenix.
What the RFP means: this is a change-detection budget question dressed as a feature.
The instinct is to re-fetch everything at the highest cadence, which is how collection budgets die. The economics that work: per-result pricing makes daily refreshs a linear decision (a full 100,000-listing sweep in one metro is about $50 at the volume rate, not a “let me check the traffic budget” conversation), and structured status fields make delta-detection trivial — you diff records, not HTML.
A good answer separates the pipeline: high-frequency deltas on hot inventory (status flips, price cuts, new listings), low-frequency completeness checks on the long tail, and scheduled collection jobs for both rather than cron scripts you maintain. Red flag: pricing that makes full refreshs feel expensive — if daily sweeps require an apology email to finance, the architecture fights your requirements.
What the RFP means: image collection at scale, the budget line that surprises teams.
Listing images are storage, bandwidth, and deduplication questions. A good answer: the same record-based architecture (fetch structured records, diff image URLs, pull only changed assets), object-storage delivery, and record-level pricing on the metadata path so the expensive path — bytes — only runs on actual change. For teams that also need visual understanding models (staging detection, photo quality scoring), the same vendor’s dataset catalog serves pre-built image-text records from about $0.25 per 1,000 records — the training-side counterpart to the collection pipeline, in one account.
Red flag: a flat “per GB of media” line with no change-detection strategy.
What the RFP means: this is a search-visibility question wearing a data-lawyer costume — because half these signals live in how properties and agents surface in search, not just on portals.
The serious proptech roadmap now includes: monitoring what appears for “homes in [suburb]” queries (portals, indexers, and — increasingly — answer-layer placements), tracking agent-brand SERP presence, and timing market-entry intelligence with search demand. The SERP monitoring solution is the fit: scheduled structured collection of organic results, local pack presence, and ads at roughly $0.70 per 1,000 responses, geo-pinned per market, delivered as records that join into the same warehouse as listing data. A continuous SERP data crawling job replaces the manual “check Google from incognito” routine that every market-research team quietly maintains.
Red flag: a data vendor whose answer to visibility questions is “that’s a different tool.”
What the RFP means: you need to survive your own legal review and your next enterprise deal.
A good answer here is concrete: documented opt-in sourcing for residential pools (Thordata describes its model this way), rate-limit discipline built into managed collection rather than left to your engineer’s conscience, and a deletion process with stated turnaround. If your requirement is a signed enterprise agreement with named SLAs and DPAs, that’s an enterprise-motion vendor’s strength — and a legitimate one; the published self-serve model above serves technically self-sufficient teams, and neither posture is a proxy for quality.
Red flag: either direction — refusing to discuss provenance, or refusing to discuss what a contract can’t give you.
What the RFP means: total week-to-first-data matters more than any feature line.
Annotated example of the call the winning architecture makes:
from thordata import Thordata

client = Thordata(api_key="YOUR_API_KEY")

def metro_sweep(city: str, page: int = 1):
    result = client.scrape(
        scraper="zillow_listings",       # maintained parser, stable schema
        query=f"{city},AZ",
        geo="US-AZ",                      # collected as a local would see it
        output_format="json",
    )
    for listing in result.records:
        warehouse.upsert({
            "mls_like_id": listing["zpid"],
            "price": listing["price"],
            "status": listing["status"],  # for sale | pending | off
            "days_on_market": listing.get("days_on_market"),
            "photos_hash": hash(tuple(listing["photo_urls"])),
            "collected_at": result.created_at,
        })
The comment that matters: every field here is the vendor’s maintenance problem, not yours. Portal redesigns are their outage, not yours.
A useful evaluation rubric weights these five questions most heavily: (1) does the vendor maintain parsers with a stable schema, (2) does geo fidelity survive an audit in your worst metro, (3) does per-result pricing make your target refresh cadence cheap enough to not argue about, (4) does the same account cover the long tail of sites with raw proxy capability, and (5) is provenance documented in writing. Two platforms typically score (1) and (3) with a single product; the ones that score all five — collection, pre-built scrapers, unlocker for the hostile 5%, SERP-side monitoring, and record-priced datasets — are the ones that shrink your vendor count without shrinking your risk. Run the free trial credits against one metro, one week, one warehouse table — and let the join between listing data and search-visibility data make the argument the RFP couldn’t.
 Looking for
Top-Tier Residential Proxies?您在寻找顶级高质量的住宅代理吗?
Buy Residential Proxies: What to Check Before You Order
Compare residential proxy loca ...
Greta
2026-09-17
逐工作負載的 Bright Data 遷移指南(你不需要全部搬走)
整家供應商的遷移會失敗;逐工作負載的路由會贏。Bright ...
Xyla Huxley
2026-09-17
買影片資料集之前:14 個幫你省下一季白費工程的問題
多數影片資料集的採購會失望,原因都一樣三樣:標題數字的意思跟 ...
Xyla Huxley
2026-09-17
語音資料的五個迷思:以及聲音團隊實際需要的東西
語音與聲音模型在生產環境失敗的原因,多半可以追溯到五個關於訓 ...
Xyla Huxley
2026-09-17
你的 SEO 儀表板說一切正常,你的 AI 搜尋能見度說:才不是
品牌能見度已經分裂成兩層:經典的十條藍色連結 SERP,以及 ...
Xyla Huxley
2026-09-17
你的連鎖餐廳 Google 商家資料,正在悄悄壞掉:多店據點監控現場指南
擁有 200 家分店的品牌,問題不是「一個 Google 商 ...
Xyla Huxley
2026-09-17
How to Test a Residential Proxy: Speed, Location, and Reliability Checklist
Test residential proxy speed, ...
greta
2026-09-16
Evaluating a Scraping API on Engineering Criteria, Not Marketing Claims: Oxylabs and Thordata, Rubric-Style
Vendor evaluations drift to wh ...
Xyla Huxley
2026-09-16
Does Your Product Work in São Paulo? A Geo-Testing Lab Notebook, With Providers Compared
Teams ship localized products ...
Xyla Huxley
2026-09-16