Top Scraping API Providers: How to Compare Your Options
This page is published by Thordata, one of the products compared.
The top scraping API providers depend on the data you need: Thordata offers a Web Scraper API, ScraperAPI focuses on SERP collection, and Bright Data offers both a SERP API and datasets. Their prices use different units—credits, requests, or records—so the lowest advertised rate may not represent the lowest cost for a given job. This guide is for buyers comparing collection methods rather than provider names alone. It shows which billing units and trial results to compare before choosing a service.
What does a scraping API handle?
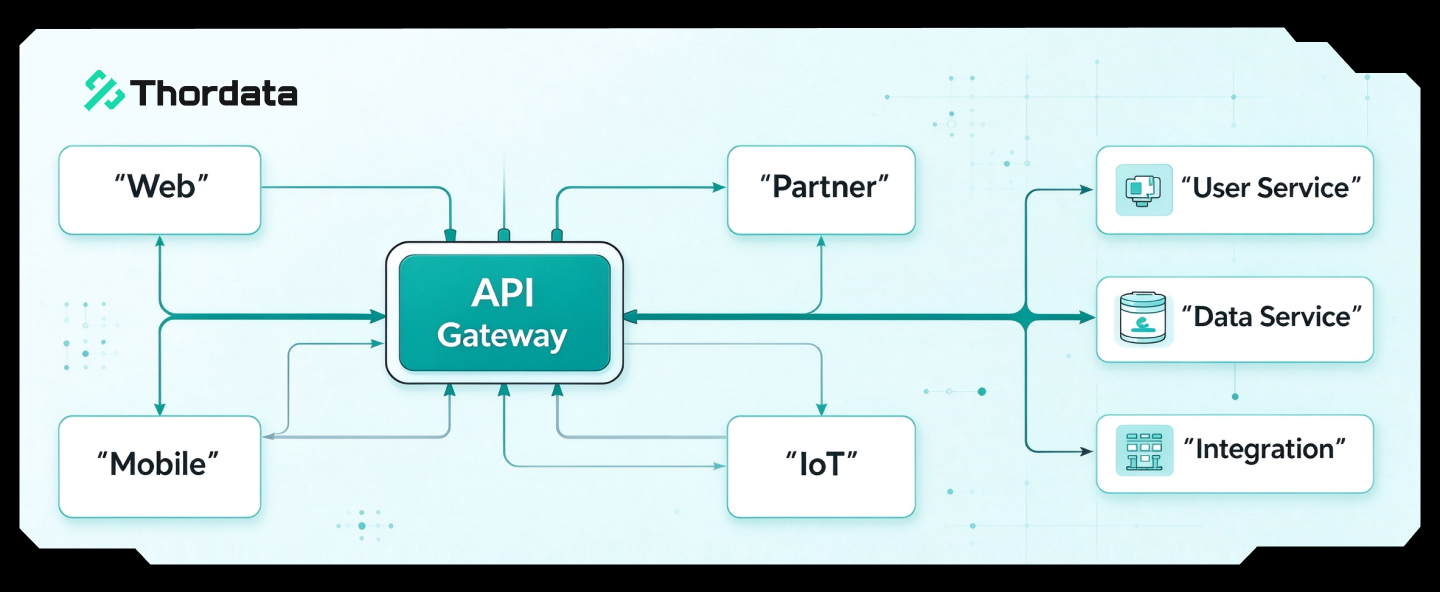
A scraping API accepts a target URL and returns a fetched page or extracted data; managing a scraping stack yourself means operating the browser or HTTP client, proxies, retries and parsing code. For buyers comparing top scraping API providers, the practical distinction is how much of that work the API handles, rather than whether it can fetch a page.
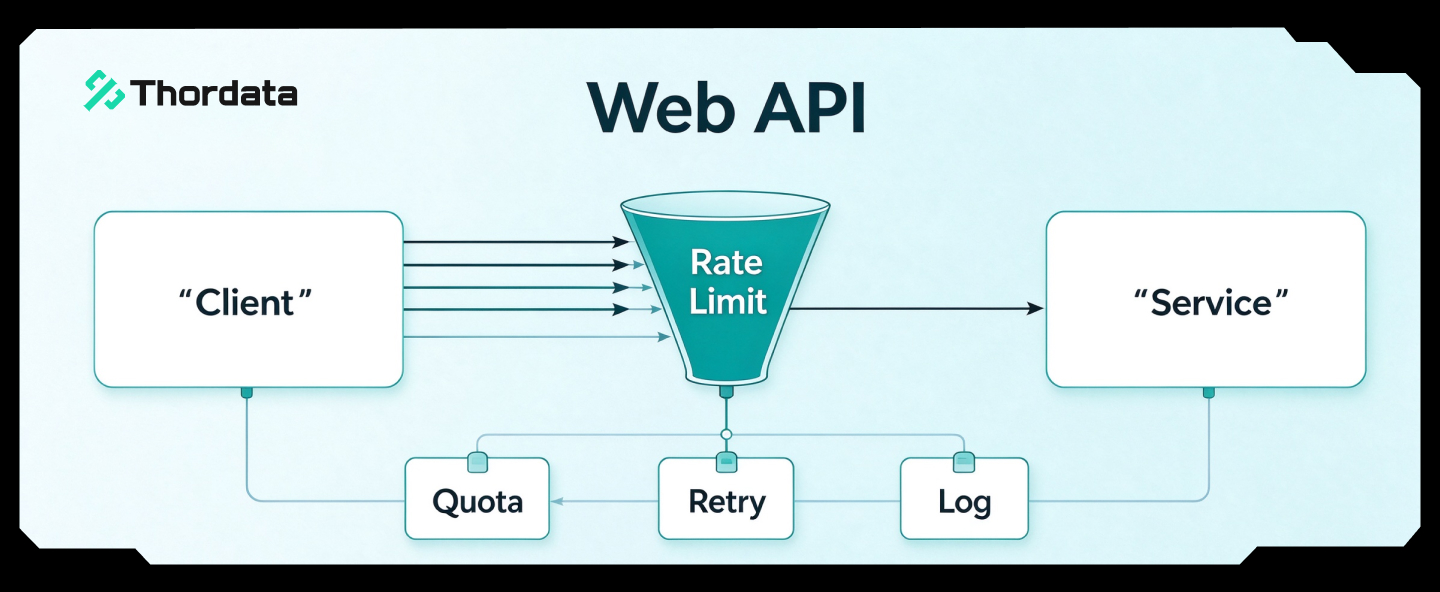
Check whether an API renders JavaScript before extraction, retries failed requests, rotates proxy IPs and returns structured fields instead of raw HTML. ScraperAPI, for example, handles IP blocking, CAPTCHAs and parsing for Google search results. Thordata offers a Web Scraper API alongside separate proxy and Scraping Browser products, so the access method can match the work your application already performs.
An API can be simpler when a job needs parsed results from many URLs but has no team to maintain browser sessions and proxy rotation. A self-managed stack gives you direct control over those components, at the cost of operating them.
How should providers be compared?
Compare scraping API providers by the data each returns, the unit charged, documented limits and integration options. Those specifications belong in a table; response time and extraction quality belong in a common test. A SERP API that returns parsed search results and a web scraper that collects page data solve different tasks, so a price per credit alone cannot rank them.
| Criterion | Thordata Web Scraper API | ScraperAPI SERP API |
|---|---|---|
| Capability | Web scraping tools | Organic and paid search results |
| Billing, as of October 2026 | $30 for 30,000 credits; $125 for 150,000; $500 for 750,000; $1,500 for 3,000,000 | $49/month for 100,000 API credits |
| Integration | API | In-house scrapers or Scraping API |
The listed capabilities are documented features, not results measured under identical conditions. To compare performance:
Send each service the same easy pages and protected pages, with identical locations, concurrency and timeouts.
Record response time, the share of requests returning successful responses, and the share yielding usable extracted fields separately. A successful HTTP response with missing fields is not usable data.
Which providers fit different scraping needs?
Thordata and Apify fit scheduled collection; Bright Data and ScraperAPI have documented search-results workflows; Oxylabs covers scheduled video-data collection. For rendered search pages, Bright Data’s SERP API includes JavaScript rendering. Zyte and ScrapingBee belong on the shortlist, but the workflow evidence used for this comparison does not establish which of these tasks they support.
| Provider | Documented workflow | Fit and boundary |
|---|---|---|
| Thordata | Web scraper for scheduled or batch YouTube extraction | Choose for structured video, transcript or comment data; its Google Videos SERP API is a separate product. |
| Bright Data | SERP API with JavaScript rendering and JSON or HTML output | Choose for rendered search results. |
| Oxylabs | Video-data scraper with scheduled jobs and cloud delivery | Choose for recurring video collection. |
| Zyte | — | Workflow fit is not established here. |
| ScraperAPI | SERP API for organic and paid results | Choose for parsed search results. |
| ScrapingBee | — | Workflow fit is not established here. |
| Apify | YouTube actors with schedules, webhooks and structured exports | Choose for configurable recurring collection; capabilities depend on the actor. |
How do billing models affect the choice?
Billing units can change which scraping API costs less for the same workload. Thordata’s Webpage package counts responses, Bright Data’s SERP API counts requests, and ScraperAPI sells API credits. Those units are not interchangeable: a workload with retries or failed requests may consume more billable units than the number of usable records it produces.
Before comparing rates, account for retries, rendering and unsuccessful requests. Bright Data counts each executed SERP API call as a request and includes JavaScript rendering and automatic retries. Thordata’s web scraper tools are a separate product line from its Webpage response packages.
| Cost-model field, as of October 2026 | Thordata Webpage | Bright Data SERP API | ScraperAPI SERP API |
|---|---|---|---|
| Listed paid package | 10,000 responses for $13 | $1.50 per 1,000 requests, pay as you go | 100,000 API credits for $49/month |
| Unit to count in a trial | Responses | Executed requests | API credits |
Run a small workload with representative pages and record billable units per usable result. That measured ratio makes the headline rates comparable.
What should a trial verify?
A scraping API trial should show whether each provider returns the required fields from representative URLs under the same conditions. Use a fixed URL set with ordinary pages and difficult pages, specify identical fields and output formats, and record usable results, failed requests and response times. A provider passes only if its output meets the extraction requirements without manual repair.
Run the URL set with the same field definitions for every provider. Compare returned values against the source pages, not merely against a successful HTTP status.
Include pages that require JavaScript rendering, location-specific results or a continuing session where those conditions matter. Record CAPTCHA responses, retries and whether a changed IP disrupts the session.
Follow each provider’s setup documentation, then examine error messages, available support paths and controls for handling personal data. For Thordata, the Web Scraper product page is the starting point for evaluating its extraction workflow.
Use a final checklist: usable fields, reliable operation under the required settings, and a billing unit that makes failed or incomplete requests understandable.
How to choose
Match the purchase to the output you need. A scraping tool returns collected data, while a proxy supplies an IP connection for a scraper you operate. If your team needs structured results without managing that collection workflow, choose a scraper API; if it already runs a scraper, compare proxy plans instead.
If you need YouTube comments in scheduled batches, choose Thordata’s web scraper, because its comments scraper accepts up to 10K URLs per batch and delivers results through an API or cloud storage.
If you need Google Videos results rather than YouTube comment records, choose Thordata’s Google Videos SERP API, because it returns titles, links, key moments and snippets.
If you need search, channel data and transcripts in one run, choose Apify’s YouTube Data Scraper, because it accepts URLs and search queries; transcripts require US residential IPs.
If you need a ready-made YouTube dataset instead of live collection, choose Bright Data, because it offers video, comment and channel-profile records with scheduled updates.
Thordata’s comments scraper suits teams with known targets and recurring collection. It is not the right product for buying historical records.
FAQ
Which are the best web scraping API providers in 2026, and what do they cost?
Thordata, ScraperAPI, Bright Data, Oxylabs and Apify are options to compare, with Zyte and ScrapingBee also on the shortlist; the choice depends on the data and workflow you need. As of October 2026, Thordata’s Web Scraper API packages start at 30,000 credits for $30, ScraperAPI’s SERP API lists 100,000 credits for $49 per month, and Bright Data’s SERP API lists pay-as-you-go requests at $1.5 per 1K. Apify prices its YouTube Scraper by search request, page or retrieved transcript, while Oxylabs offers a video data scraper; compare billable units against usable results before choosing.
Is a scraping API the same as a proxy service?
No. A scraping API accepts a collection request and returns data, while a proxy service supplies IP connectivity for software that handles the collection itself. Choose proxies when an existing scraper already manages parsing and retries; choose an API when those tasks should sit outside the scraper. Thordata offers both web scraping tools and residential proxies, which are billed by GB rather than API credits.
Can a scraping API retrieve video files, or only video data?
A scraping API’s output depends on the product: Thordata’s Google Videos SERP API returns fields such as titles, links, thumbnails and snippets, not the video file. For video or audio files, Thordata’s video datasets include media files, while Decodo’s video downloader delivers requested media to customer storage. If the job is search-rank monitoring, use the SERP API; if the job requires media for analysis, use a file-delivery product.
 Looking for
Top-Tier Residential Proxies?