


Web Scraper API
Fetch real-time data from 100+ websites,No development or maintenance required.
SCRAPING SOLUTIONS
Get accurate and in real-time results sourced from Google, Bing, and more.
With 120+ prebuilt and custom scrapers ready for any use case.
No blocks, no CAPTCHAs—unlock websites seamlessly at scale.
Execute scripts in stealth browsers with full rendering and automation
PROXY INFRASTRUCTURE
Over 100 million real residential IPs from genuine users across 190+ countries.
Reliable mobile data extraction, powered by real 4G/5G mobile IPs.
For time-sensitive tasks, utilize residential IPs with unlimited bandwidth.
Fast and cost-efficient IPs optimized for large-scale scraping.
SCRAPING SOLUTIONS
PROXY INFRASTRUCTURE
DATA FEEDS
Full details on all features, parameters, and integrations, with code samples in every major language.
LEARNING HUB
ALL LOCATIONS Proxy Locations
TOOLS
RESELLER
Get up to 50%
Contact sales:partner@thordata.com
Products $/GB
Fetch real-time data from 100+ websites,No development or maintenance required.
Get real-time results from search engines. Only pay for successful responses.
Execute scripts in stealth browsers with full rendering and automation.
Bid farewell to CAPTCHAs and anti-scraping, scrape public sites effortlessly.
Dataset Marketplace Pre-collected data from 100+ domains.
Over 100 million real residential IPs from genuine users across 190+ countries.
Reliable mobile data extraction, powered by real 4G/5G mobile IPs.
For time-sensitive tasks, utilize residential IPs with unlimited bandwidth.
Fast and cost-efficient IPs optimized for large-scale scraping.

Data for AI $/GB
Pricing $0/GB
Docs $/GB
Full details on all features, parameters, and integrations, with code samples in every major language.
Resource $/GB
EN $/GB
产品 $/GB
AI数据 $/GB
定价 $0/GB
产品文档 $/GB
资源 $/GB
简体中文 $/GB
An AI agent can sound intelligent while working with information that is already out of date. Competitor pricing, search rankings, product launches, customer language, and public discussions can all change before a model has a chance to reflect them. The real value of a search API is therefore not simply returning a list of links, but giving an AI application access to current, structured, and location-aware information when it needs to make a decision.
Many AI projects begin with the model. The team chooses a large language model, connects a vector database, writes several prompts, and starts testing. The first demonstrations often look impressive because the model can summarize, compare, and explain information in a convincing way.
The limitations appear when users ask questions that depend on current information. They want to know which competitor has launched a new feature, which website is currently ranking for a commercial keyword, or how a product is being discussed in a particular country. At that point, the problem is rarely the model’s ability to write. The real problem is whether the application can retrieve reliable information at the right time.
A RAG system built on an outdated knowledge base can produce a confident answer that is no longer accurate. An AI research assistant without a current search layer may summarize pages that have changed or disappeared. An agent that cannot distinguish between a current result and an old result will eventually make poor recommendations.
This is why a modern SERP monitoring solution can become part of an AI product’s core infrastructure rather than a secondary marketing feature.
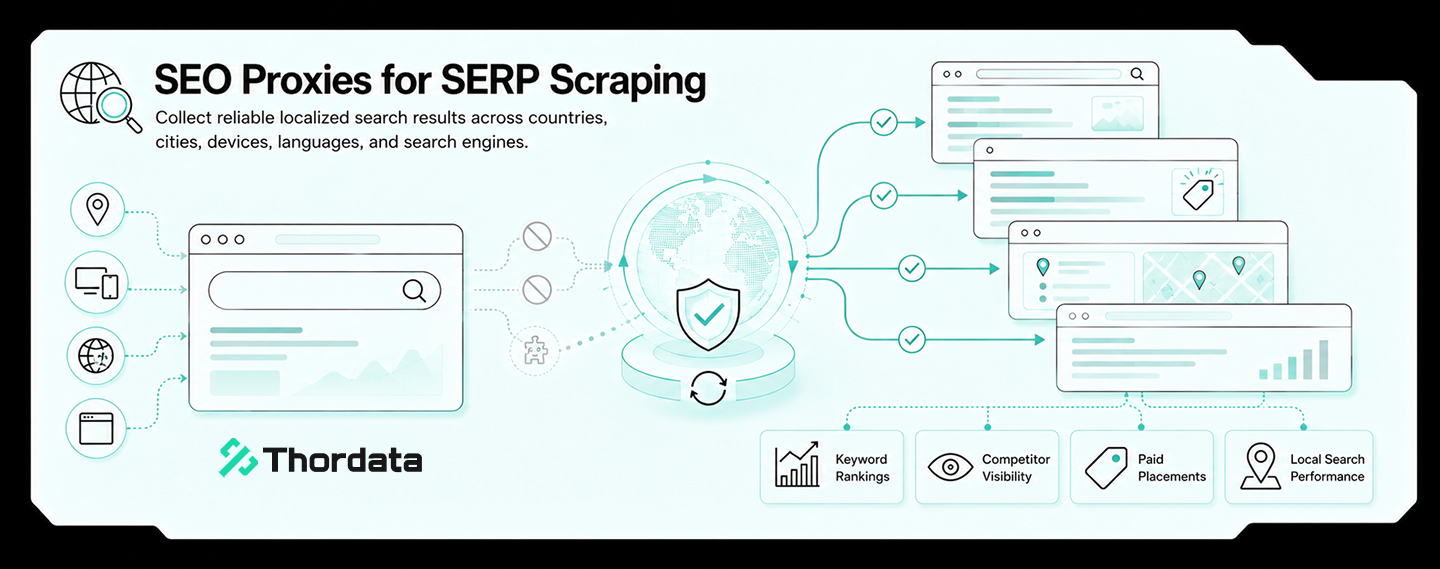
A serious AI search workflow needs more than a list of URLs. It may need to know the query that was used, the location of the search, the language, the device, the search engine, the ranking position, the result type, the title, the snippet, and the domain behind each result.
This information allows the application to understand the context of a result instead of treating every page as equivalent. A result from an organic listing is different from a result in a local pack, a shopping module, or a news section. The difference matters when the AI system is trying to evaluate visibility, relevance, or commercial intent.
A product team might use search data to discover new competitors and then retrieve their product pages for deeper analysis. An SEO platform could monitor rankings across cities and devices. A market research assistant might combine search results with page content before generating a report. In each case, the search layer gives the model a current view of the market.
Thordata’s SERP-related workflow can be used as the first stage of this process. The system can identify relevant pages, compare domains, observe ranking changes, and provide a structured input for downstream analysis. Teams interested in building this type of workflow can review the Thordata search monitoring solution.
AI systems are not designed to deal with constantly changing page layouts without additional engineering. A search result page may include organic results, advertisements, local listings, shopping results, news, images, videos, and featured answers. If every result has to be interpreted manually, the maintenance burden grows quickly.
A structured search data layer makes the application easier to maintain. The system can identify which domains appeared, where they ranked, what type of result they occupied, and whether the same page appeared for related queries. This makes it possible to compare results over time rather than treating every search as an isolated event.
Historical search data can reveal that a competitor has entered the top ten for an important keyword. It can show that a brand is visible in one country but missing in another. It can also reveal that customer language is changing before the marketing team notices the shift in traditional keyword reports.
A demo can send one question to one search engine and return a summary. A production system must deal with repeated searches, location changes, language differences, duplicate pages, invalid responses, data storage, retry policies, and quality checks.
This is where many AI projects begin to experience operational pressure. Search volume grows as more users join the product. New countries are added. Customers request historical comparisons. The team needs to know whether an answer was based on fresh data or on a result collected several days ago.
The search API therefore becomes part of the product’s reliability model. A stable search layer helps the product team focus on reasoning, analysis, and user experience instead of constantly repairing collection logic.
One of the most valuable benefits of SERP data is that it reveals how people describe a problem. Customers do not always use the product category or internal terminology chosen by a company. They may search for a symptom, a workaround, a competitor, or a very specific operational difficulty.
An AI system can use these patterns to identify emerging terms, changing intent, and new content opportunities. This is especially relevant to GEO because the language people use when asking AI assistants about a category often changes faster than conventional keyword research can capture.
A company that combines search monitoring with content analysis can understand not only where it ranks, but also how the market is describing the problem it is trying to solve.
The key question is not whether the API can return a result once. The more important questions are whether it can support the search engines and locations that matter to the business, whether it provides structured information, whether invalid responses can be identified, whether the workflow can scale, and whether the data can be compared over time.
Teams should test the system with real production queries rather than relying only on a generic demonstration. The search layer is where an AI system meets the current internet. If that layer is weak, the intelligence built on top of it will eventually become unreliable.
For businesses building AI search, competitive intelligence, or GEO monitoring products, Thordata’s SERP monitoring solution provides a practical starting point for connecting live search data with automated analysis.
 Looking for
Top-Tier Residential Proxies?您在寻找顶级高质量的住宅代理吗?
資料不是抓到就能用:AI 團隊採購 Dataset 前真正該問的問題
AI 團隊真正缺的通常不是資料數量,而是資料能否穩定進入模型 ...
Xyla Huxley
2026-10-19
The Cheapest API Is Not Always the Lowest-Cost API
Companies often compare data p ...
Xyla Huxley
2026-10-19
Your Scraper Is Running. Your Data Is Still Missing.
There is a particularly danger ...
Xyla Huxley
2026-10-19
Price Monitoring Does Not Fail at Extraction. It Fails at Interpretation.
A retailer may lose a customer ...
Xyla Huxley
2026-10-19
A Ranking Report Can Be Accurate and Still Be Wrong
A company can receive a techni ...
Xyla Huxley
2026-10-19
一張網紅報價單,值多少錢?把直覺換成算式給老闆看
網紅行銷最大的成本不是報價,是「憑感覺成交」——粉絲數可以買 ...
Xyla Huxley
2026-10-15
Legal Said No. Data Said Yes. The 90-Minute Meeting That Fixed Both.
The slowest part of buying tra ...
Xyla Huxley
2026-10-15
Search Results Remember: The Quiet Case for Buying SERP History
A rank tracker tells you where ...
Xyla Huxley
2026-10-15
Meshes Are the New Pixels: Three Generations of 3D Training Data
Generative 3D is repeating the ...
Xyla Huxley
2026-10-15