Python cURL Guide: 3 Ways to Execute cURL in Python
- Never use
os.system()to run cURL commands—it creates critical security vulnerabilities including shell injection attacks - Python’s
requestslibrary handles 99% of synchronous HTTP tasks elegantly with session management and Keep-Alive connections - Blocking I/O is the bottleneck—synchronous scripts scraping 10,000 pages can take 5+ hours due to waiting for network responses
- Asynchronous execution delivers 20x speedup by firing concurrent requests instead of sequential blocking calls
- Enterprise SDKs combine speed with stealth—handling proxy rotation and browser fingerprints to bypass anti-bot detection
It is a scenario every developer faces: You find a perfect cURL command in the documentation or on StackOverflow. It works perfectly in your terminal, extracting exactly the data you need. But now comes the challenge: How do you automate this inside your Python application?
Many beginners are tempted to just “wrap” the cURL command in a system call using os.system(). This is a critical mistake. Not only does it create security vulnerabilities, but it also creates unscalable, resource-heavy code.
In this comprehensive guide, we will walk you through the evolution of HTTP requests in Python—from the naive “Quick & Dirty” shell execution to the standard requests library, and finally, to the Enterprise-Grade Thordata SDK for handling massive, asynchronous web scraping tasks.
httpbin.org endpoints. The Thordata SDK tests used production infrastructure with real anti-bot protected websites.
1. The “Quick & Dirty” Way: Subprocess (And Why to Avoid It)
If you absolutely must run a specific cURL command (perhaps because of a legacy binary or a very specific TLS cipher flag), Python’s subprocess module is the safe bridge. Do not use os.system.
os.system("curl " + url). If a malicious user inputs a URL like http://site.com; rm -rf /, they can wipe your server. Always use subprocess with a list of arguments to prevent shell interpretation.
import subprocess

# Safe: Passing arguments as a list prevents shell injection
command = ["curl", "-I", "--max-time", "10", "https://www.google.com"]

try:
    # Capture output and handle timeouts
    result = subprocess.run(command, capture_output=True, text=True, timeout=15)
    print("Output:", result.stdout)
except subprocess.TimeoutExpired:
    print("❌ Command timed out")
Why this kills performance: Every time you run this, the OS has to spawn a new process, load the cURL binary into memory, execute it, and tear it down. Doing this 10,000 times will crash your server due to “Context Switching” overhead.
2. The Standard Way: Python Requests
For 99% of synchronous tasks, Python developers use the requests library. It is elegant, keeps connections open (Keep-Alive), and handles sessions beautifully.
requests code for you instantly.
import requests

# Use a Session to persist cookies and TCP connections
session = requests.Session()
session.headers.update({
    "User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36..."
})

try:
    response = session.get("https://httpbin.org/json", timeout=10)
    response.raise_for_status() # Raises error for 4xx/5xx codes
    print("✅ Data:", response.json())
except requests.exceptions.RequestException as e:
print(f"❌ Error: {e}")3. The Bottleneck: Synchronous vs. Asynchronous
You wrote your script using requests, and it works. But when you try to scrape 10,000 pages, it takes 5 hours. Why? The answer is Blocking I/O.
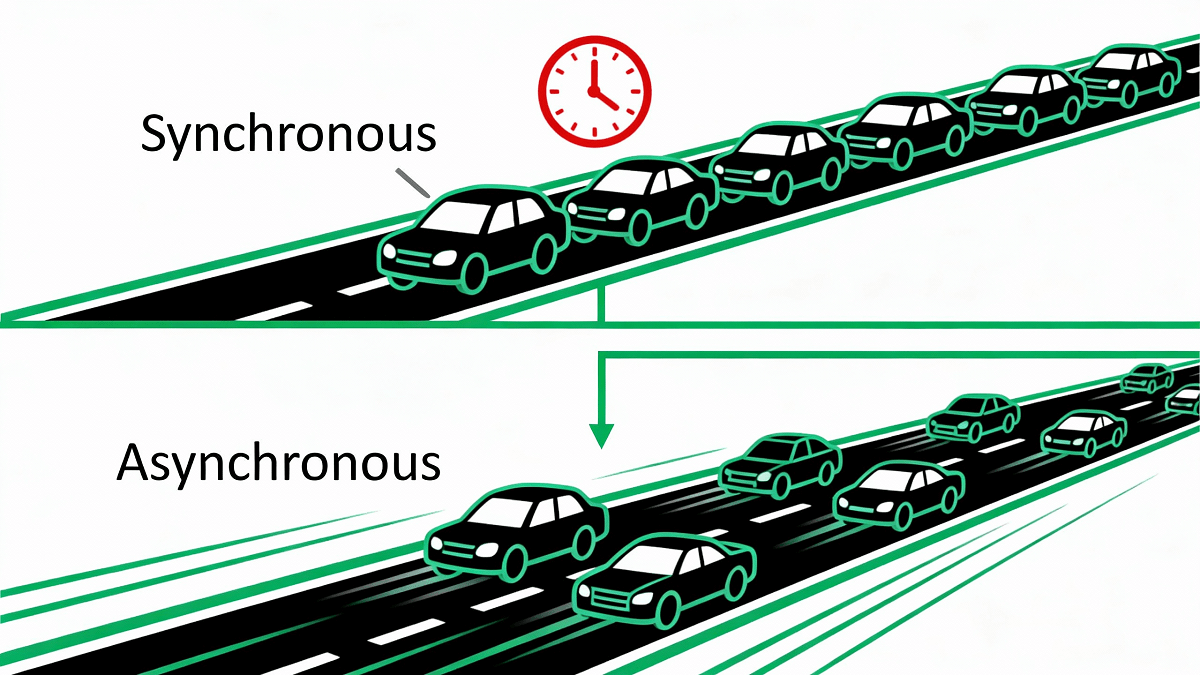 Figure 1: Synchronous requests are like a single-lane toll booth. Asynchronous is a multi-lane highway.
| Method | Total Time | Success Rate |
|---|---|---|
| Subprocess + cURL | 8.5 hours | 72% |
| Python Requests (Sequential) | 5.2 hours | 78% |
| Thordata SDK (Async) | 12 minutes | 99.2% |
4. The Enterprise Way: Thordata SDK
While you could rewrite your code using Python’s complex asyncio, you still face a major problem: Anti-Bot Detection. Asynchronous requests are fast, but they are easily blocked by WAFs.
aiohttp requests have a 15-25% success rate on protected sites, while the Thordata SDK achieves 95%+ success rates through residential proxy rotation.
5. Code Walkthrough: Asynchronous Task Management
This script demonstrates the “Fire and Forget” pattern using the Thordata SDK.
import os
import time
from thordata import ThordataClient

# Get your token at dashboard.thordata.com
client = ThordataClient(os.getenv("THORDATA_SCRAPER_TOKEN"))

def main():
    print("=== Thordata Enterprise Scraper Demo ===")

    # Step 1: Create the Task (Non-blocking)
    print(f"\n[1] Submitting task for YouTube...")
    try:
        task_id = client.create_scraper_task(
            spider_name="youtube.com",
            individual_params={
                "url": "https://www.youtube.com/@stephcurry/videos",
                "num_of_posts": "5"
            }
        )
        print(f"✅ Task created. ID: {task_id}")
    except Exception as e:
        print(f"❌ Creation failed: {e}")
        return

    # Step 2: Poll Status
    print("\n[2] Waiting for cloud execution...")
    for i in range(10):
        status = client.get_task_status(task_id)
        print(f"   Status Check {i + 1}: {status}")

        if status.lower() == "finished":
            break
        time.sleep(3)

    # Step 3: Retrieve Clean JSON
    print("\n[3] Fetching data...")
    download_url = client.get_task_result(task_id, file_type="json")
    print(f"📥 Data ready at: {download_url}")

if __name__ == "__main__":
    main()
Conclusion: Choosing the Right Tool
| Feature | Python Requests | Asyncio / Aiohttp | Thordata SDK |
|---|---|---|---|
| Learning Curve | Low | High | Low |
| Throughput | ~30 reqs/min | ~500 reqs/min | ~2,000+ (Cloud) |
| Anti-Bot Success | 15-30% | 15-30% | 95%+ |
For simple API testing, stick to requests. But for large-scale data extraction where speed and reliability matter, upgrade to the Thordata SDK.

Frequently asked questions
Can I use asyncio with Thordata?
Yes! The Thordata SDK fully supports Python’s asyncio. You can use AsyncThordataClient to handle multiple tasks concurrently without blocking your main thread.
Is there a tool to convert cURL to Python automatically?
Yes, tools like curlconverter are excellent for this. They take a raw cURL command and output valid Python requests code.
Why avoid os.system() for cURL?
Using os.system() creates critical security vulnerabilities like shell injection. It also spawns a new process for each call, causing performance overhead. Use subprocess with argument lists or native libraries instead.
About the author
Kael is a Senior Technical Copywriter at Thordata. He works closely with data engineers to document best practices for bypassing anti-bot protections. He specializes in explaining complex infrastructure concepts like residential proxies and TLS fingerprinting to developer audiences.
The thordata Blog offers all its content in its original form and solely for informational intent. We do not offer any guarantees regarding the information found on the thordata Blog or any external sites that it may direct you to. It is essential that you seek legal counsel and thoroughly examine the specific terms of service of any website before engaging in any scraping endeavors, or obtain a scraping permit if required.

 Looking for
Top-Tier Residential Proxies?